The sophisticated veneer of a modern, automated factory floor often conceals a chaotic reality where critical decisions still rely on a fragmented patchwork of manual spreadsheets and brittle PDF documents. While internal operations have reached unprecedented levels of digital maturity, the communication channels that bridge the gap between manufacturers and their vast networks of suppliers remain stuck in a pre-automation mindset. This discrepancy creates a profound bottleneck at the very edge of the enterprise, where incoming information is often treated as a peripheral IT concern rather than a core logistics attribute. As organizations strive for greater resilience, the focus has shifted toward the first mile of data—the point where external inputs enter the corporate ecosystem—to solve the persistent issues of fragmentation and error propagation.
The Rising Crisis of First-Mile Data Fragmentation
Benchmarking the Global Data Management Gap
The scale of the current data management crisis is underscored by the fact that approximately 80 to 90 percent of all enterprise information remains unstructured. For the average manufacturer, this data exists in the form of disparate PDF invoices, lengthy email chains, and manual spreadsheets that require significant human intervention to process. Despite heavy investments in Enterprise Resource Planning (ERP) and Manufacturing Execution Systems (MES), the data that feeds these platforms is often incomplete or misaligned with internal requirements. This creates a state of “visibility asymmetry” where a company might possess real-time data on its own machine performance but remain completely blind to the quality and accuracy of the data arriving from its tier-two and tier-three suppliers.
This internal-external disconnect has measurable consequences for workforce productivity and operational efficiency. Industry statistics reveal that professionals within the supply chain sector currently lose between 30 and 70 percent of their time to manual data reconciliation. Instead of focusing on strategic sourcing or production optimization, these employees are tasked with verifying part numbers, correcting date formats, and cross-referencing shipping notices against purchase orders. This hidden labor cost is rarely accounted for in traditional performance metrics because the work is absorbed by the existing staff, effectively masking a systemic failure in data integration as mere “busy work.”
The gap between data generation and data usability also complicates the ability to maintain a single version of truth across the supply chain. When information is trapped in unstructured formats, it cannot be easily audited or analyzed for long-term trends. Consequently, companies often make high-stakes procurement decisions based on “stale” or partially corrected data sets. The reliance on manual touchpoints not only slows down the speed of business but also introduces a significant margin for human error, which becomes increasingly dangerous as the complexity of global trade continues to grow throughout 2026 and into the future.
Real-World Impacts on Production and Delivery
A common misconception in modern logistics is the belief that “digital” communication is synonymous with “structured” data. While a supplier might have replaced their old fax machines with email-delivered PDFs, the underlying readability for an automated system has not improved. A PDF is essentially a digital picture of a document; it lacks the semantic structure required for an ERP to understand the relationships between fields. Without an automated way to parse this information, the manufacturer still relies on a person to read the image and type the data into a system. This creates a deceptive sense of modernization that lacks the actual benefits of high-speed, machine-to-machine integration.
These structural failures are most visible during peak season surges, when the sheer volume of transactions removes the “human buffer” that normally compensates for poor data. During standard periods, a few dozen data exceptions per day might be manageable for a small team of planners. However, when order volumes quadruple, those exceptions scale linearly, overwhelming the staff and leading to a total breakdown in visibility. This is when the lack of automated data integration stops being an administrative annoyance and starts being a production-stopper. When a human can no longer keep up with the manual corrections, the system begins to ingest errors, leading to late shipments, stockouts, and strained customer relationships.
The most insidious part of this fragmentation is the “multiplication effect” of defects throughout the production cycle. A single unit-of-measure error on an inbound shipping notice—such as listing “cases” where the system expects “eaches”—can propagate through the entire organization. This error flows into forecasting models, which then overestimate demand; the master schedule then allocates components that do not exist, and the inventory system commits stock that is functionally invisible. By the time the error is caught on the assembly line, the cost of correction has grown exponentially. In this environment, data freshness and accuracy are not just IT metrics; they are the fundamental components of physical supply chain resilience.
Expert Perspectives on Integration Hurdles and AI Limitations
Insights from industry leaders like Tim Bond, Chief Product Officer at Adeptia, highlight that digitization often halts abruptly at the “property line” of the manufacturer. While a company can control every schema and sensor within its own four walls, it cannot dictate the IT standards of a thousand different trading partners. This lack of control has led to a fragmented landscape where the inbound edge of the enterprise is the most neglected part of the digital transformation journey. Manufacturers find themselves in a position where they must adapt to the technological limitations of their weakest supplier, rather than pulling those partners into a more sophisticated data ecosystem.
The complexity of this problem is further exacerbated by the way networks scale. Adding a 101st supplier does not simply add another row to a database; it adds a new integration surface with its own unique formats, semantics, and error profiles. The cost of managing a partner network is often non-linear because each new connection requires custom mapping and manual oversight. As companies attempt to diversify their supply bases to avoid regional disruptions, they inadvertently create a “scaling of the mess.” This administrative overhead becomes a barrier to agility, making it difficult for businesses to pivot to new partners quickly when market conditions shift.
Furthermore, there is a critical consensus among experts that Artificial Intelligence cannot act as a universal fix for unreliable data. Modern AI models lack the human reflex to question “plausible but wrong” inputs. If an inbound file contains a quantity that is ten times the normal order but formatted correctly, a human might pause to verify it, whereas an AI model will simply process it as fact. This vulnerability is the primary reason why roughly 60 percent of AI projects are projected to face abandonment through 2026. Without AI-ready data that is structured, validated, and governed at the point of ingestion, the most advanced algorithms will only serve to accelerate the speed of bad decision-making.
The Future of Autonomous Supply Chain Networks
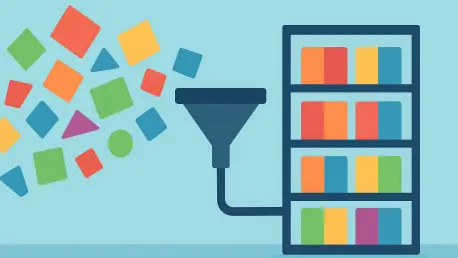
The industry is beginning to move away from the traditional model of “per-partner code,” transitioning instead toward canonical data models and reusable templates. This shift allows manufacturers to map any incoming data format—whether it is a specialized EDI document or a simple CSV file—to a single, standardized internal structure. By using these reusable patterns, companies can reduce the time required to onboard a new supplier by up to 90 percent. This approach prioritizes flexibility at the edge while maintaining a rigid, clean data environment within the core systems, allowing the business to expand its network without a corresponding increase in IT headcount.
Another significant trend is the adoption of “upstream validation,” where data is quarantined and checked at the point of ingestion rather than after it has entered the ERP. This change in architecture forces the sender to correct errors in real-time, effectively moving the burden of data quality back to the source. If a supplier sends an invoice with a missing part number, the system automatically rejects it with a specific error message before it can ever disrupt internal planning. This proactive gatekeeping ensures that the data driving autonomous systems is verified and accurate, providing the necessary foundation for true supply chain automation.
As these systems evolve, they are also incorporating “progressive automation” to capture manual corrections and turn them into documented patterns for machine learning. Every time a human corrects a field, the system learns the logic behind that correction, eventually automating the repair of similar defects in the future. This creates a self-healing data loop that improves over time. Additionally, forward-thinking companies have begun to use “data stress-testing” to simulate high document volumes and malformed data sets. By finding the break points in their digital infrastructure before the peak season arrives, manufacturers can ensure that their systems are as resilient as their physical warehouses.
Summary and Strategic Outlook
In the final analysis, the transition toward integrated supply chain data required a fundamental shift in how organizations viewed their information flows. Manufacturers eventually recognized that data freshness and structural integrity were not merely technical requirements but were, in fact, essential logistics attributes. They moved away from viewing data as a byproduct of a transaction and started treating it as a primary asset that required its own instrumentation and governance. By prioritizing the inbound edge of the enterprise, companies were able to eliminate the “visibility asymmetry” that had previously left them vulnerable to external disruptions and manual errors.
Strategic leaders discovered that true supply chain resilience depended on the ability to onboard a diverse range of partners without incurring massive administrative overhead. They achieved this by implementing canonical data models and upstream validation protocols that ensured all incoming information was clean and actionable before it reached critical planning systems. This approach allowed businesses to scale their operations rapidly, responding to market fluctuations with a level of agility that was impossible in the era of manual data reconciliation. The focus shifted from merely digitizing existing documents to creating a truly structured and automated data environment.
Ultimately, the manufacturers that thrived were those that instrumented their inbound edge and made data readiness a prerequisite for their digital transformation initiatives. They successfully bridged the gap between their high-tech internal operations and the messy reality of their supplier networks. By treating data integration as a strategic priority, these organizations ensured that their investments in AI and automation delivered on the promise of total visibility and speed. They moved toward a future where the supply chain functioned as a cohesive, autonomous network, capable of absorbing shocks and scaling with ease because the information at its core was finally reliable.